Running FiGet in production
A single container with SQLite runs with no settings at all. Behind a reverse proxy, with more than one replica, or on a
server other people rely on, these are the settings that matter. Every key below is also an environment variable, with
__ for each : (FiGet:PublicBaseUrl is FiGet__PublicBaseUrl).
Behind a reverse proxy
FiGet:PublicBaseUrl: thehttps://address clients use. Required behind a proxy: every URL in a protocol answer, the sign-in redirect URI and the copy buttons are built from it. With anhttps://address the sign-in cookies are also marked Secure.ASPNETCORE_FORWARDEDHEADERS_ENABLED=true, so the client's address and scheme come from the proxy. It does not take the host name from the proxy; that is whatPublicBaseUrlis for. The switch trusts whoever connects, so only the proxy may be able to reach the container's port: a network policy, or a port that is not published. When requests arrive withX-Forwarded-Proto: httpsbut FiGet would buildhttp://addresses, it logs a warning once: current NuGet clients refusehttp://resources under anhttps://source.- The proxy's body limit must be at least
FiGet:Limits:MaxAssetSizeMB(1024 MB by default), or large uploads are refused before they reach FiGet.
Database and replicas
- SQLite for one container; SQL Server as soon as there is more than one replica. Set
FiGet:Database:ExpectedReplicasto the replica count: FiGet refuses to start with SQLite above 1. - Migrations run at start under the database's migration lock, so every replica may start at once.
- Retention, pruning the audit log and sweeping abandoned uploads run on one replica at a time, which takes a lease in the database. Nothing to configure.
- Rate limits are counted per replica.
- Admin → System reports what is running, how many copies of it, how much room is left on the volume, and what the database is doing. See below.
The key ring
Sign-in cookies, antiforgery tokens and the stored client secrets of sign-in providers are protected by a key ring that lives in the database, so every replica shares it.
FiGet:DataProtection:MasterKey: 32 random bytes in base64 (openssl rand -base64 32) that encrypt that key ring, from a secret (on OpenShift an ESO-synced Secret). Without it the start logs a warning; with more than one replica FiGet refuses to start without it.- Setting it later encrypts the keys already stored, in place: sessions and provider secrets stay valid.
- Keep it. Without it, or with another one, the ring cannot be read: every session ends and provider secrets have to be entered again.
Storage
- One volume for FiGet's storage (
FiGet:Storage:Root), ReadWriteMany when there is more than one replica. FiGet:Storage:TempPathon that volume or on a scratch volume, not on the container's own writable layer: uploads and packages downloaded from upstreams are buffered there while they are checked, and an installer is large.- Shares for asset directories under one folder,
FiGet:Assets:SharesRoot. See Asset directories. - A UNC path works as the storage root on Windows (
\\server\share\figet), tried with pushes, downloads and asset uploads. - Admin → Storage check lists stored files no package, symbol or asset names - left by a failed delete or a stop between a file and its record - and removes them on request. Files written in the last hour are never counted.
Secrets
- Upstream credentials are environment variables whose names start with
FIGET_UPSTREAM_(FIGET_UPSTREAM_GALLERY); an upstream names the variable, never the secret. Any other name is refused. A bare key is sent with the user namefiget; for an upstream that checks the user too, write the secret asuser:password. Only administrators set an upstream's address and credential; feed managers edit its name, patterns and switch, and add the known public galleries. FiGet:Auth:BootstrapAdminToken, if used, a long random value from a secret.- The database connection string from a secret.
- A sign-in provider's client secret is entered on its page and stored encrypted with the key ring.
Sign-in providers
- With a provider anyone can register at (Google, a multi-tenant Entra registration), set Allowed email domains, or turn Make an account at a first sign-in off and connect accounts from their profiles.
- Keep one local super admin:
/account/login/localis the way in when the provider cannot be reached.
Network
- Allowed networks per feed or asset directory, on its settings page, when a feed should only answer internal clients.
- Fetch by URL reaches the internet directly by default. Behind an egress proxy set
FiGet:RemoteFetch:Proxytogether withFiGet:RemoteFetch:AllowedHosts. - Anonymous rate limits are per client address. Many clients behind one address, such as an office's NAT, can hit
them: raise
FiGet:RateLimits:AnonymousRequestsPerMinute, or give that client a key, since requests with a valid key are not limited. A request that sends no credential to a feed that needs one is not counted either: NuGet clients with stored credentials send each request once without them and answer the 401.
The image
ghcr.io/rousseauxy/figet:latest, or a version tag such as 1.2.1. One tag carries linux/amd64 and linux/arm64,
built on a runner of each architecture. It runs as a non-root, arbitrary UID in group 0, listens on 8080, and writes
only to /data and /tmp.
There is no shell in it, and no package manager. The runtime is a chiseled rootfs holding .NET, ICU, the time-zone
database, glibc and OpenSSL — and not the Ubuntu packages a web server never calls. A registry scanner measured against
it on 2026-10-01 reported nothing at all for util-linux (mount, bsdutils, libsmartcols1) or PAM, because they are
not installed rather than patched; what remains is glibc and OpenSSL, which FiGet genuinely uses.
So docker exec … sh and oc rsh do not work. Almost nothing needs them: the container's log is on stdout, the
database and the package files are on the volume you mounted, and Admin → System answers how large the database is,
how much room is left, which copies are running and when each job last ran. For the rest, oc debug with another image
mounting the same claim, or build yourself a copy with a shell — the runtime base is a build argument:
docker build -f deploy/Dockerfile --build-arg RUNTIME_IMAGE=mcr.microsoft.com/dotnet/aspnet:10.0.13 -t figet:shell .
Releases up to 1.7.0 also published a -shell tag built this way; from 1.7.1 only the chiseled image is published.
Backup and recovery
Two things hold the state, and a restore needs both from the same moment:
- The database — feeds, versions, accounts, keys, the audit log, and the key ring that protects sessions.
- The storage root — the package and symbol files, and the files of asset directories that are not folder-backed. A folder-backed directory is the share itself and is backed up wherever that share is.
Back the database up the way your provider expects (SQL Server backup; for SQLite, sqlite3 figet.db ".backup …",
which is safe while FiGet runs — copying the file while it is being written is not). Restore both, start FiGet, and it
applies any migrations the newer binary needs. A database restored without its files leaves versions whose downloads
answer 404: Admin → Storage check lists files no row names, and pushing an identical package again restores its
file (for a version whose row is at least an hour old).
If the key ring is lost, everyone is signed out and has to sign in again; nothing else is damaged. Set
FiGet__DataProtection__MasterKey so the ring survives a rebuild of the database.
When nobody can sign in any more — the last administrator's account is locked, disabled or forgotten — set
FiGet:Auth:Recovery:UserName and FiGet:Auth:Recovery:Password and restart. That account is created if it does not
exist, enabled, unlocked, made super administrator, given that password, and asked to choose a new one at sign-in. It
runs on every start while the settings are there, and the log warns each time: remove them once you are back in.
What the system page tells you
Admin → System reports and changes nothing. It counts no rows and walks no files — every figure is a page count, a file size, a list of migrations or a handful of rows — so it costs about as much as a health check and can be refreshed at will.
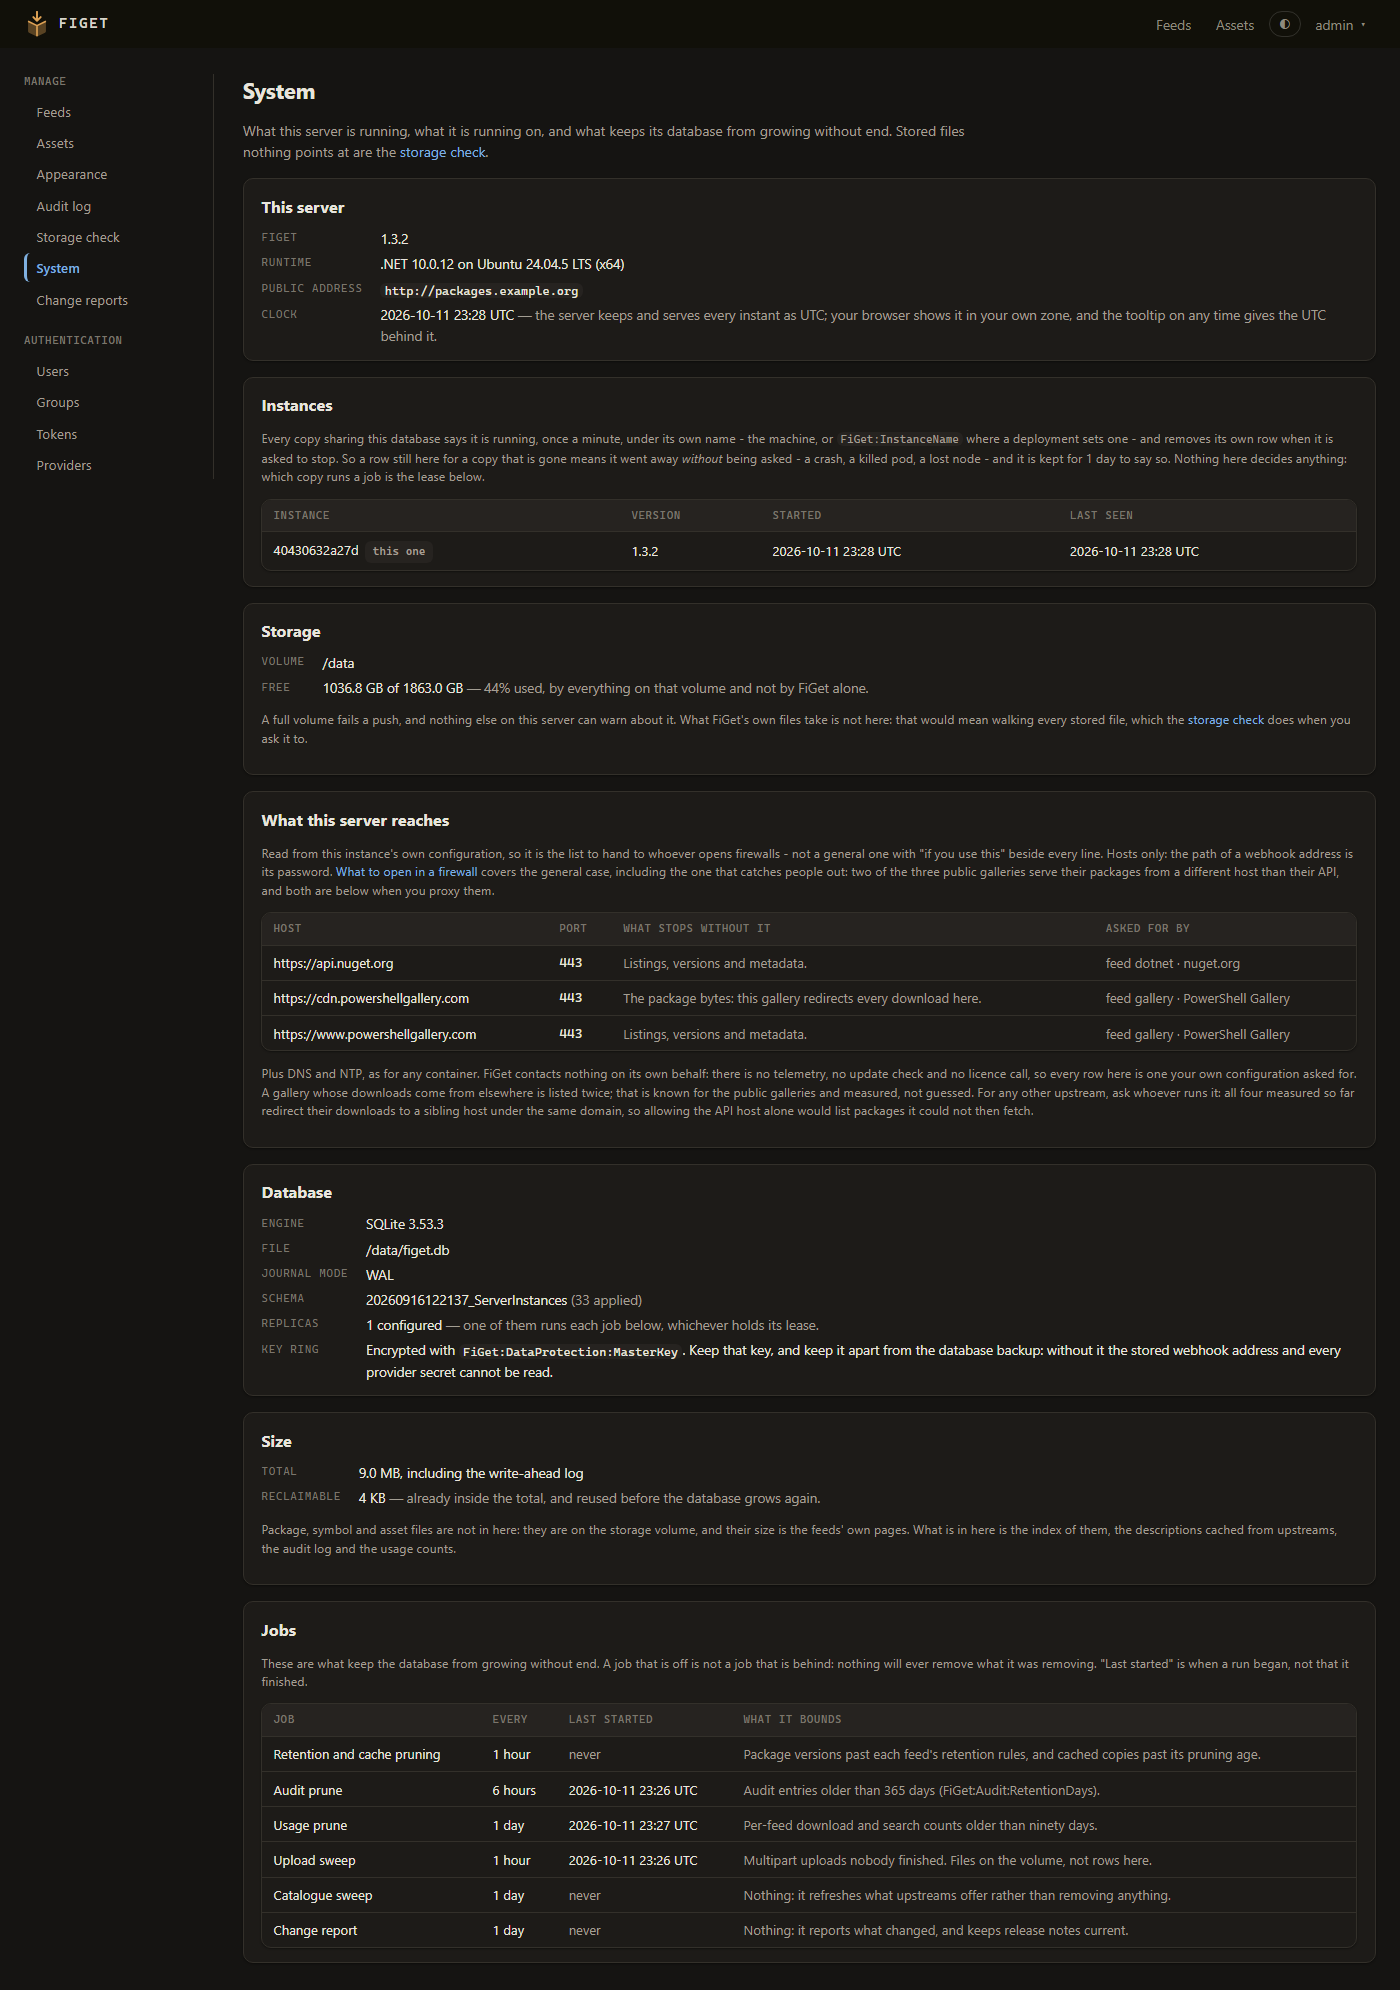
- What is running: the FiGet version, the .NET runtime, the operating system and the processor architecture (useful
on a mixed fleet, since the image is built for
amd64andarm64), the public base URL, and the clock in UTC. - Which copies are running. Every instance writes a row once a minute saying it is there, with its version and when
it started, and removes its own row when it is asked to stop. So a restart and a rolling update leave nothing
behind, and a row still there for a copy that is gone means it went away without being asked — a crash, a killed
pod, a lost node. That row is kept for a day to say so, marked quiet once it has missed three heartbeats.
Each row is named after the machine, or
FiGet:InstanceNamewhere a deployment sets one. The name is a place, not a process: a copy that restarts under the same name takes its own row back instead of adding one. The page warns only when fewer copies are running thanFiGet:Database:ExpectedReplicas— something that should be there is not. More copies than expected, or two versions at once, is what a rolling update looks like from here, so it is stated plainly rather than raised as an alarm. These rows are a report: nothing reads them to decide anything, so a stale one costs a line on a page and not a job that stops running. -
How much room is left on the volume the storage root is on. A full volume fails a push, and nothing else on this server can warn about it. It is the volume's free space, not FiGet's own footprint: what FiGet uses would mean walking every stored file, which the storage check does on request.
-
What you are connected to: the engine and its version, the database file or
server / database, and the journal mode (SQLite) or recovery model (SQL Server). The connection string is never shown: the page is given the host and the catalogue and nothing else, so it cannot print a password. - How large it is, and how much of that the engine will reuse before it grows again. On SQLite the write-ahead log is
counted in the total, because that is a second file and the volume fills up with the sum. On SQL Server the transaction
log is its own line, and a
FULLrecovery model with no log backup is the usual reason a log dwarfs its data. - Which migration the schema is on. Migrations waiting to be applied are reported loudly: that means this build expects a newer schema than the database has, and anything the new schema added will fail.
- Every background job: its interval, when it last started, and what stops growing when it stops. A job switched off
with
FiGet:Jobs:*is marked — that is not a job running late, it is a table with nothing bounding it any more.
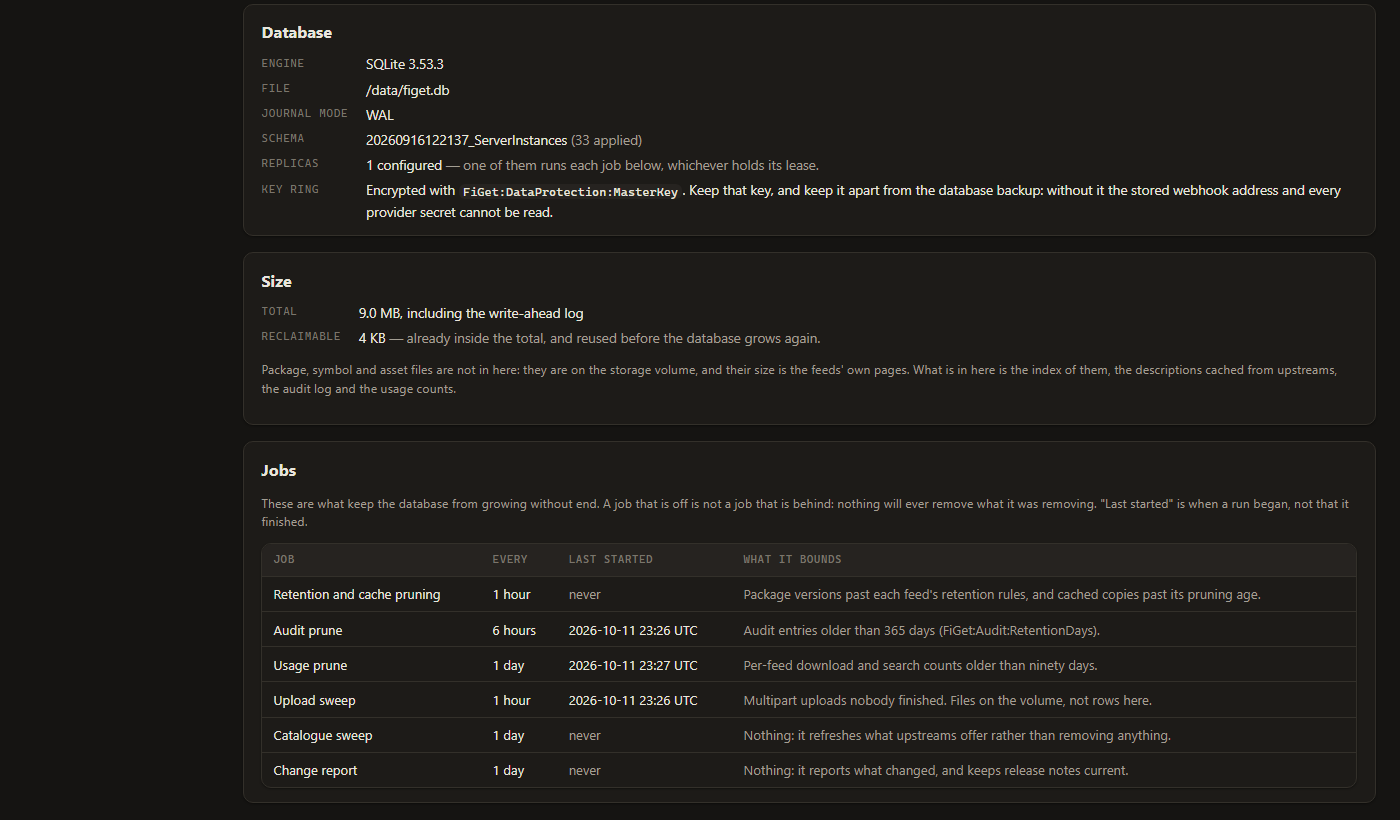
Stray package, symbol and asset files are the storage check. "Last started" means a run began, not that it finished.
One volume, two clusters
A volume shared by instances on different clusters needs one thing understood: each cluster assigns its own user id range, so the same workload runs as a different user on each one. What they share is the group — every pod runs with group 0 and new files carry it.
FiGet therefore sets its own umask to 0002 at start-up, before it can create anything: files are written 0664 and
directories 0775, so whichever instance wrote a file, an instance on the other cluster can replace or delete it. The
start-up log says so once:
It is not a setting. A mask that denies the group is wrong on a shared volume and harmless on a private one, so there is no deployment that wants the choice.
The mount itself is still yours to get right: a umask governs what a process creates, not what it is handed. The
volume must be group-owned and group-writable before FiGet starts, which on OpenShift is what the namespace's fsGroup
does automatically.
Without it, anything that rewrites rather than appends fails depending on which cluster serves the request and which one wrote the file — deleting a version, retention and cache pruning, overwriting an asset — while the database row says the work was done. Intermittent and asymmetric, which is the worst way for it to present.
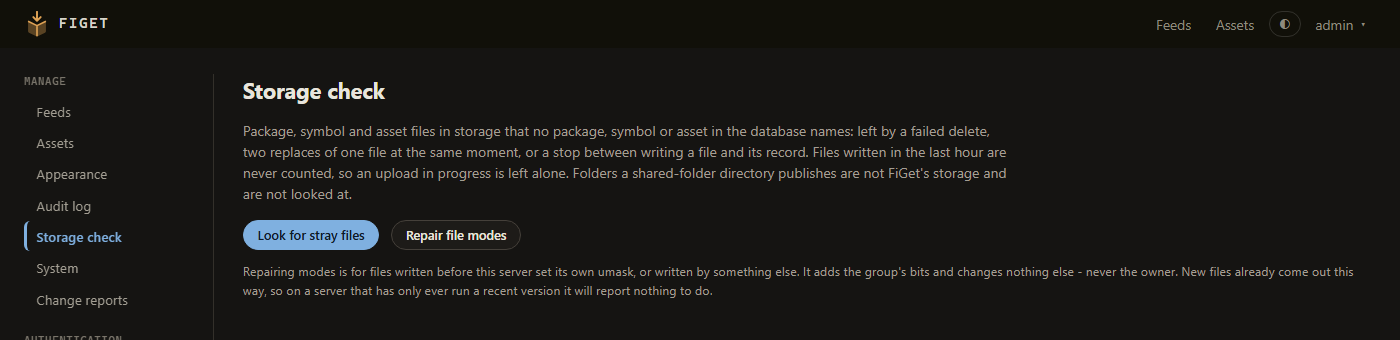
Files written by a version before 1.3.2 keep their old modes. Fix them once from Admin → Storage check → Repair file modes, which adds the group's bits to what it finds and changes nothing else — never the owner, never the bits for everyone else. Run it on each cluster: only an owner may change a mode, so each instance repairs what it wrote, and the page tells you how many it had to leave alone and why.
FiGet deliberately does not do this at start-up. It would walk a whole package volume over NFS on every pod start and, worse, silently achieve nothing for the files the other cluster owns — which is exactly the half you need fixed. Run it twice, once per cluster, and the second run on each reports nothing left to do.
Health
| URL | Answers 200 when | Point this at |
|---|---|---|
/health/live |
the process is running, nothing else checked | a liveness probe: restart the container when this fails |
/health/ready |
the process and the database answering | a readiness probe, and whatever watches whether the server is usable |
Both return the plain text Healthy, and a non-200 otherwise, so anything that checks a status code is enough. Neither
needs a token, so a monitor outside the cluster can read them.
Watch /health/ready, not /health/live. The live check stays green through a database outage, which is the one
failure you most want to hear about. A gallery you cannot reach shows in neither: see
what to open in a firewall.